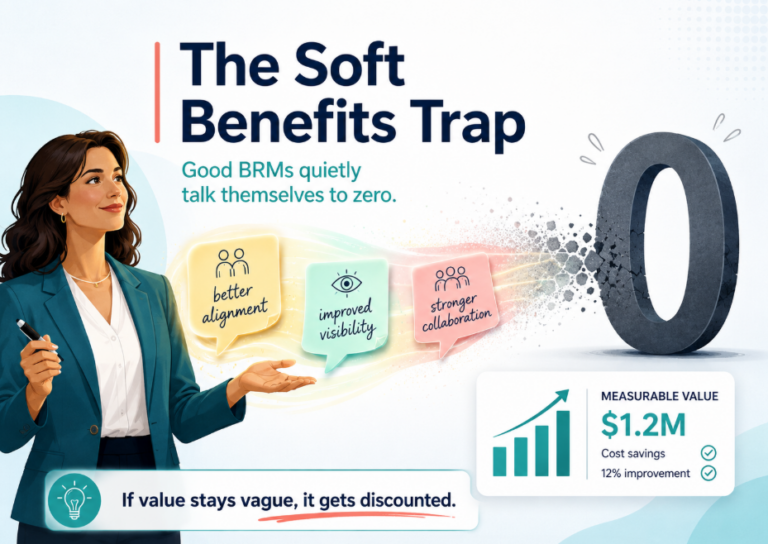
Listen to how technical and relationship leaders describe their own work in funding conversations, and you will hear a specific phrase over and over. “The hard savings are around forty thousand, and then there are some soft benefits on top of that.” It sounds humble. It sounds honest. It sounds like someone being careful not to overclaim.
It is also the exact moment the value evaporates.
I have spent twenty years watching capable people undercut their own initiatives, and the “soft benefits” phrase is the most common self-inflicted wound I see. The person saying it thinks they are being credible. What they are actually doing is standing in front of the finance lead and handing them permission to round half the value down to nothing.
Part 1: What “Soft” Actually Signals
Here is what you think “soft benefit” means: a real benefit that is harder to measure precisely.
Here is what the person holding the budget hears: a benefit the presenter could not be bothered to quantify, and therefore one I am free to discount to zero.
Those are not the same message, but you only control the first one. The second one is what determines whether your number survives. When you label something “soft,” you are not adding a caveat. You are making a ranking decision on your own initiative, and you are ranking the benefit at zero. Finance simply accepts the ranking you volunteered.
The tragedy is that most “soft” benefits are not soft at all. Reduced rework, faster decision cycles, lower analyst burnout, fewer escalations, better data trust across a business unit. Every one of those has a defensible dollar figure sitting underneath it. It is not there because someone stopped digging one layer too early and reached for the word “soft” as a shortcut.
Part 2: The Anatomy of a Benefit That Got Away
Take “this saves the team a lot of manual effort.” That is the sentence that dies as a soft benefit. Now watch it get resurrected.
How many people? Say four analysts. How many hours per week does the manual work consume? Say six each. That is twenty-four hours a week, roughly twelve hundred hours a year. What is the loaded hourly cost of an analyst at your organization? Call it eighty dollars. You are now looking at just under one hundred thousand dollars in annual capacity, and not one number in that chain was invented. Every figure is one your organization already knows or can produce in an afternoon.
That is the difference between a soft benefit and a hard one. It is not the nature of the benefit. It is whether you did the arithmetic. “Soft” is almost never a property of the value. It is a description of how far you stopped short of quantifying it.
And here is the part that should sting a little: the analyst-hours example is the easy one. The genuinely valuable benefits, the strategic ones, are the ones people abandon fastest because the chain looks longer. So the most important value in your portfolio is precisely the value most likely to get waved away as “soft.”
Part 3: Stop Discounting Your Own Work
The fix is not to overclaim. Overclaiming gets you caught, and getting caught once costs you credibility for years. The fix is to build the traceable chain from the technical work to the dollar figure, so that when you say a number, you can defend every link of it, and you never have to reach for “soft” as a hedge.
That discipline, turning vague benefit language into quantified, defensible figures without inflating anything, is a learnable method. It is the core of what I wrote Quantify Your Impact to teach. The book exists because I watched too many strong BRMs and product owners talk themselves down to zero in rooms where their work deserved a real number. Every “soft benefit” you have ever mentioned had a figure underneath it. This book is how you find it.
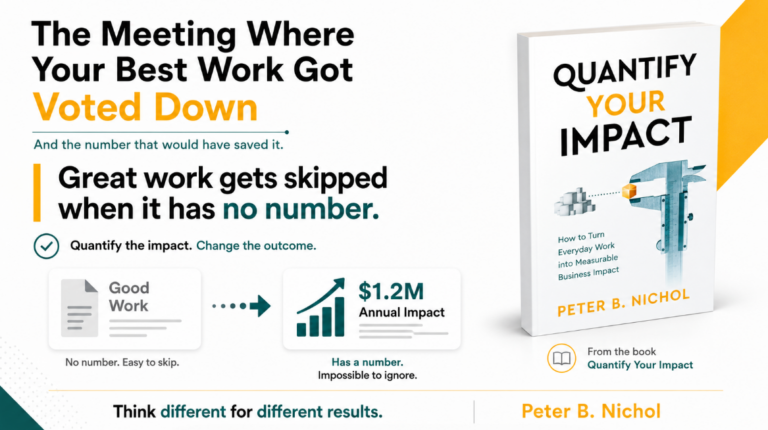
There is a particular kind of quiet that happens in a budget review. Not the good quiet. The kind where you finish presenting the initiative you are proudest of, the one your team spent two quarters building, and the room just moves on. No hostility. No debate. Someone nods, says “let’s revisit next cycle,” and the next line item comes up. Your work was not rejected. It was skipped.
I have watched that happen to genuinely excellent work more times than I can count. And after twenty years of sitting on both sides of that table, as an engineer, a CIO, and now leading data and analytics portfolios, I have stopped believing the problem is the work.
Part 1: The Work Was Never on Trial
Here is the uncomfortable truth. In the room where funding gets decided, nobody is evaluating your architecture. Nobody is admiring your integration design or your data model or the elegance of how the pipeline handles edge cases. Those things are real, and they matter, but they are not what is being weighed.
What is being weighed is a list of numbers. Every initiative that survives that meeting arrives as a number: a cost avoided, a cycle time reduced, a revenue stream protected, a risk priced. The ones that arrive as descriptions, however impressive, get filed under “sounds valuable, can’t rank it.” And you cannot fund what you cannot rank.
This is the trap that catches strong technical leaders specifically. The better your work is, the more you assume it speaks for itself. It does not. In a budget review, work does not speak. Numbers speak. Your work sat there, mute, next to six other line items that had learned the language.
Part 2: What Actually Happened in That Room
Play the scene back and watch the mechanics. The finance lead is not being difficult. They are being forced to sort. They have a fixed pool of money and a stack of requests that exceeds it, and their entire job in that hour is to produce a ranked order. Anything that cannot be placed in that order gets deferred, not because it lacks value, but because it lacks a coordinate.
Your competitor for that funding, the initiative that got approved while yours got skipped, was very likely not better work. It was better positioned. Someone attached a defensible number to it early, socialized that number before the meeting, and walked in with a figure the finance lead could drop straight into the ranking. That is the whole game. The number does not have to be big. It has to exist, and it has to hold up when someone pushes on it.
This is why I keep saying the leader who keeps their funding is rarely the one with the strongest portfolio. It is the one who puts a number on the table before anyone asks for it.
Part 3: The Number You Should Have Had
So what was the number that would have saved your initiative? Not a made-up one. Not a hopeful projection you cannot defend. A quantified, traceable figure that connects the technical work you did to a business outcome someone in that room already cares about.
Most technical leaders do not have that number for a simple reason: nobody ever taught them how to build one. Quantifying the value of data, analytics, and integration work is a specific skill, and it is not intuitive. It requires a repeatable method for turning “we improved the pipeline” into “we reduced X by Y, worth Z annually.” That translation is learnable, and once you have the method, you never walk into a budget review naked again.
That method is exactly what I wrote Quantify Your Impact to teach. It is the first book in the BRM Accelerator Series, and it exists because I got tired of watching good people lose funding for good work simply because they never learned to price it. If your best work has ever been quietly skipped in a room full of numbers, this is the book that fixes the cause, not the symptom.
Every IT, digital, and product leader I talk to is running the same gauntlet right now. AI pilots that need a business case. Process redesigns that need a payback. Platform migrations that need a defensible ROI. Automation programs that have to land, and then be measured.
The work is real. The outcomes are real. But somewhere between the team executing and the executives funding, value evaporates. The initiative ships, the demo impresses, and six months later nobody can articulate what it was worth in a budget review.
I’ve watched that pattern repeat for twenty years, as an engineer, a CIO, and now leading data, analytics, and integration portfolios. And the leader who keeps their funding is rarely the one with the strongest portfolio. It’s the one who puts a number on the table.
For a long time I thought this was a communication problem. It isn’t.
The Diagnosis Most Leaders Get Backwards
It’s a quantification, trust, and execution problem — in that order. You can’t earn strategic trust around value you’ve never quantified. And you can’t execute against a strategic agenda you were never trusted to shape. Most leaders attack this backwards: they push for a seat at the table first, then scramble for numbers when the funding question lands. The sequence is the whole game.
Once I understood that, the fix stopped being a tactic and became a system — one I’ve been building, testing, and refining across real portfolios for years, and eventually formalized as the Quantified Impact Framework™. The hardest part wasn’t inventing it. It was realizing that no single book, course, or certification taught the three pieces together. So I wrote them.
Three Problems, Three Books
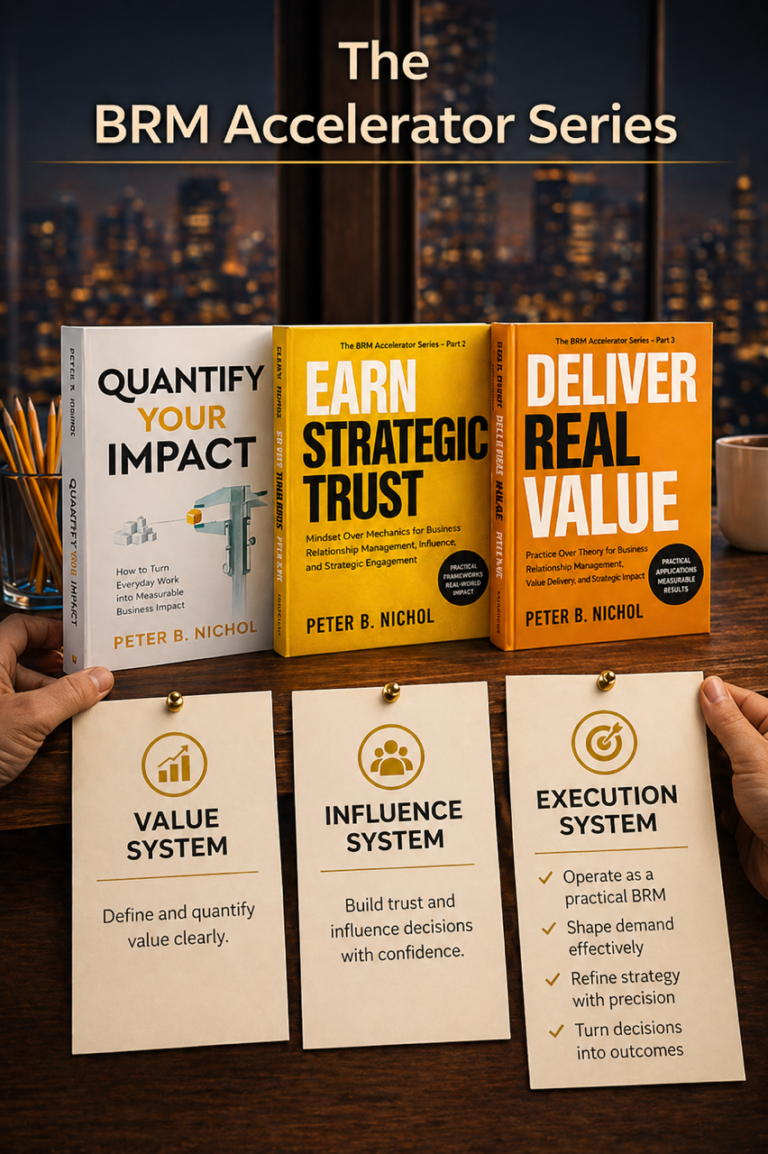
Problem one: your work is invisible at funding time.Quantify Your Impact solves this. It’s the framework book — including the exact field-by-field structure I use to turn a routine initiative into a number an executive can defend without me in the room. Hours avoided, dollars unlocked, risk retired, time recovered. Start here; everything else in the series assumes this language.
Problem two: you have numbers but no seat.Earn Strategic Trust solves this. It’s a 26-week development program covering what actually earns influence at the strategic table — stakeholder dynamics, value discovery, portfolio shaping — and why the “trusted advisor” posture most BRMs are taught quietly undermines all three.
Problem three: you have the seat but can’t convert it.Deliver Real Value solves this. A second 26-week program — the operator’s companion — that turns the theory into the weekly playbook: shaping demand, refining strategy, turning decisions into outcomes you can point to a year later.
Quantify gives you the language. Earn gives you the theory. Deliver gives you the practice. Together they’re a 52-week development arc — one read for the leader, a program for the team.
Where to Start
If any of the three problems above sounds like your Tuesday, the matching book is the entry point. If all three do — and for most IT, data, and product leaders I talk to, all three do — the series is built to be read in order. All three are on Amazon in paperback ($24.95 each):
One more thing, for readers watching AI reshape their role in real time: The Operator Shift, a field supplement to Earn Strategic Trust, tackles AI compression head-on, including an updated maturity ladder that replaces the 2015 BRM Institute model and shows how to position yourself to leverage AI rather than be replaced by it.
The work your team does is real. Make sure the room knows what it’s worth.
The story that AI will eliminate the role is wrong. The story that AI will leave it untouched is also wrong. The truth is more uncomfortable and more actionable: AI is going to compress the role into a smaller, more selective version of itself, and the practitioners who survive the compression are not the ones who learn the new tools.
Every article I read about AI and the BRM role makes one of two arguments. Either AI is going to eliminate the role within five years, or AI is going to leave the role mostly intact while making the work easier. Both arguments are wrong, and the reason they are wrong is the same. They treat AI as a tool that affects the role uniformly. It does not.
AI compresses the role asymmetrically. Some parts of the role are about to be absorbed almost completely. Other parts are about to become more valuable than they have ever been. The practitioners who survive the next three years are the ones who can tell which is which, and who shift their week accordingly before the compression catches them.
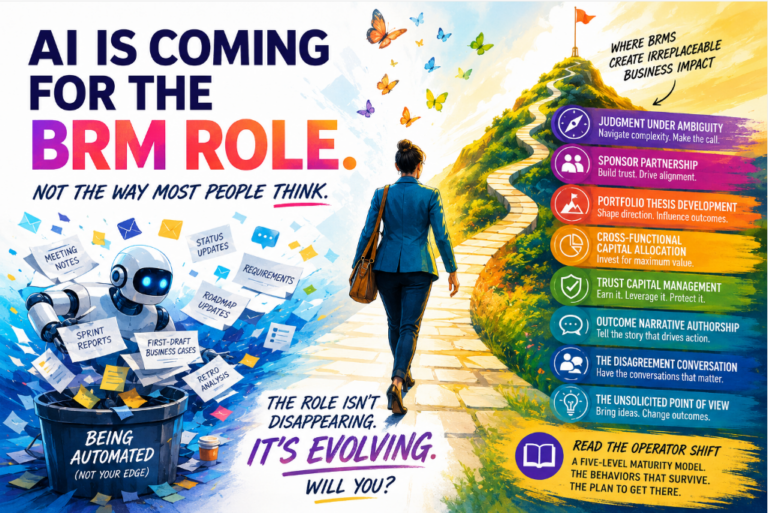
Here is the part of the role being absorbed. Translation. Requirements gathering and decomposition. Status synthesis. Stakeholder updates. Meeting notes. First-draft business cases. Sprint retro analysis. Routine roadmap maintenance. These are the activities that fill 40 to 60 percent of most BRM calendars, and they are also the activities that current and near-term AI tools already do at 70 to 80 percent of acceptable quality. Inside eighteen months, that figure will be higher. Inside thirty-six months, organizations will stop staffing these activities at the BRM level.
Here is the part of the role becoming scarcer and more valuable. Judgment under ambiguity. Sponsor partnership. Portfolio thesis development. Cross-functional capital allocation. Trust capital management. Outcome narrative authorship. The disagreement conversation in a one-on-one. The unsolicited point of view on a strategic question. These are activities AI cannot do, will not be able to do in the relevant time horizon, and that are currently underpriced because the volume of translation work has been crowding them out.
The compression is the gap between these two lists. The role is not going away. The role is getting narrower and more demanding. The same job title, in three years, will involve less of what most BRMs do today and more of what only the top quartile does today.
This is the part most career advice misses. The skill stack you need for the post-compression role is not a new skill stack. It is the existing senior skill stack, made mandatory at every level of the role. The behaviors that distinguished senior BRMs from mid-career BRMs in 2020 are about to become entry-level requirements in 2027.
The implication is uncomfortable. If your week today is 60 percent translation work, you are not going to fail because AI took your job. You are going to fail because the people promoting into senior BRM roles in 2027 spent the last three years practicing the behaviors that AI cannot do, and you spent the last three years practicing the behaviors that AI can.
The question that matters now is not which AI tools to learn. The question is which behaviors to start practicing before the compression makes them table stakes. The behaviors are knowable. They have been knowable for years. They are the behaviors that have always separated practitioners at the top of the role from practitioners in the middle of the role. The difference is that the middle of the role is about to disappear, and the practitioners currently sitting in it will either move up or out.
I have been mapping these behaviors against a five-level maturity model for several years now. The model existed before AI compression became visible as a force, and the model has not needed to change much in response to it. What AI is doing is collapsing the distance between the levels. The lower levels are being absorbed. The upper levels are becoming where the role lives.
The Operator Shift supplement lays out the model in full. The five levels, the specific behaviors at each level, the transition plan from one level to the next, and the diagnostic for figuring out where you currently operate. It is not an AI book. It happens to be the book that matters most if you are trying to survive what AI is about to do to the role.
The compression is already underway. The behaviors that survive it are the ones to start practicing now.
Not because they were wrong. Not because the team failed to execute. Because the gap between strategy approved and value realized is filled with a thousand small decisions that no one tracked, no one owned, and no one signed for. The plan landed in a deck. The deck landed in a quarterly review. The review landed in a folder. The value never landed anywhere.
This is the realization gap. And it is the single largest source of wasted IT, analytics, and transformation spend in the modern enterprise.
Deliver Real Value is the second book in the BRM Accelerator Series, and it picks up exactly where Earn Strategic Trust leaves off. Earn Strategic Trust builds the relationship foundation. Deliver Real Value builds the execution muscle. Together they describe the two halves of the modern BRM role — and neither half is enough on its own.
The book is built around one core argument: in a world where AI compresses advisory work and finance demands realized numbers, the BRMs and digital leaders who survive are the ones who can carry an initiative end-to-end through realization, not just frame it well at the start.
Inside, you will find a framework for closing the realization gap on every initiative you touch. You will find the difference between owning a roadmap and owning an outcome, and why the second is the only one that compounds. You will find the discipline of killing initiatives whose value model does not hold up, before they consume more budget. You will find the practice of signing the value case in your own name and the operational consequences of doing it.
This is a book about execution accountability in an era when AI can produce strategy faster than humans can review it. The strategic framing is now commodity. The realized outcome is the moat. If you have ever delivered a flawless project that somehow still failed to move the business, this book explains why and how to fix it.
Strategy without realization is theater. Deliver Real Value is the playbook for ending the theater and starting the work that actually moves the line.
The second book in the BRM Accelerator Series. For BRMs, product owners, and digital leaders who need their work to convert into realized business outcomes — not just well-framed strategies.
The most dangerous moment in an IT leader’s career is the moment they think they are the strategic partner.
The title says it. The org chart says it. HR says it. But sit in the actual strategy meeting and notice who speaks first, whose opinion the CEO defers to, who gets pulled into the room before the slide deck is built. If that person is not you, the title is decorative.
Strategic trust is not assigned. It is earned. And it is earned in a very specific way that almost no one teaches.
Earn Strategic Trust is the first book in the BRM Accelerator Series, and it is the foundation everything else in my work stands on. The premise is simple: there is a five-stage path from being an order taker to being a true strategic partner, and most BRMs, IT leaders, and digital executives are stuck somewhere in stage two without knowing it.
The book maps the path. It names the behaviors that move you up the ladder and the ones that hold you back. It dismantles the comfortable myth that strategic trust accumulates from doing good work over time. It does not. Strategic trust is built by specific decisions made under specific conditions — the way you frame a tradeoff, the way you handle a missed commitment, the way you tell an executive something they do not want to hear.
Inside, you will find the five archetypes of the BRM journey and how to identify which one your business partners see you as today. You will find the language patterns that signal advisory authority and the ones that signal subordination. You will find a framework for building executive credibility deliberately rather than hoping it accumulates. You will find the moments — the small, repeated, high-leverage moments — where strategic trust is actually won or lost.
This is not a leadership book. It is a practitioner’s playbook for the role that sits between IT and the business, the role that is harder than either job alone because it requires fluency in both. If you have ever felt like you were one good quarter away from being treated as a peer to the executives you serve, this book is the bridge.
The work matters less than how the work is received. Earn Strategic Trust shows you how to engineer the reception.
The first book in the BRM Accelerator Series. For BRMs, IT leaders, product owners, and digital executives who are tired of being one rung below the table where the real decisions get made.
Most IT investments fail the same way. Not in execution. In math.
A team ships a platform on time, under budget, with high adoption. The CFO asks one question at the next review: “What was the realized value?” The room goes quiet. Someone produces a slide with adoption metrics and user satisfaction scores. The CFO nods politely. The next funding cycle, that team’s budget gets cut.
This is not a delivery problem. It is a quantification problem.
For fifteen years I watched senior IT leaders, BRMs, and analytics directors build extraordinary capabilities that disappeared from the executive narrative within twelve months. The work was real. The value was real. But the number — the specific, defensible, dollar-attached figure that ties the work to a business outcome — was missing. And in an era where finance, procurement, and the board read everything through ROI, missing the number means missing the seat at the table.
Quantify Your Impact is the methodology I built across two decades of pressure-testing what actually defends an IT investment to a CFO who has never seen the platform. It is not a theory book. It is a field manual.
Inside, you will find the Quantified Impact Framework — a ten-step methodology for converting any IT, analytics, or digital initiative into a defensible value case. You will find the seven-field business value schema that finance, audit, and the board accept without rework. You will find the difference between projected value and realized value, and why most leaders confuse the two until the moment it costs them. You will find a step-by-step process for building a 3-year quantified projection that survives executive scrutiny.
This is the book I wish I had when I first sat in a budget review and could not defend a $4M investment with a number. By the end of the next chapter, you will be able to.
The work has shipped. The question is whether anyone outside your team can see it. Quantify Your Impact gives you the language, the math, and the playbook to make sure they can.
If you have ever been told your impact “speaks for itself” — and then watched it not speak loud enough — this book is for you.
A practical guide for IT leaders, BRMs, product owners, and analytics directors who need their work to land in the executive narrative. Part of the BRM Accelerator Series.
Are you doing a lot of proof of concepts, or you’re trying to figure out different ways to optimize your infrastructure and decrease costs?
Hi, I’m Peter Nichol, Data Science CIO. Allow me to share some insights.
What is hyper-converged infrastructure?
Today, we’re going to talk about hyper-converged infrastructure, also known as HCI, what it can do, and the potential benefits.
HCI is a term that I came across over the last couple of weeks. I was curious to get more involved in exactly what it was and its capabilities related to data analytics. I envisioned appliances and other technologies with built-in processors like IBM Netezza (a data warehouse appliance) and others. I was interested in what precisely this hyper-converged infrastructure could potentially achieve.
Hyper-converged infrastructure combines compute storage and networking into a single, virtualized environment. This technology takes advanced compute, RAM, and storage which you’re already familiar with. These are all elements of a hyper-converged infrastructure. You can dynamically configure and allocate compute, RAM-based, and set up different networking configurations based on your needs, all within a single unit.
This single virtualized system uses a software-defined approach to leverage dynamic pools of storage, replacing dedicated hardware.
The benefits of hyper-converged infrastructure?
First, there is less risk of vendor lock-in. The rationale is that you’re not as susceptible to vendor lock-in because you have an easily swapped-out appliance. Second, HCI solutions offer public cloud agility with the control that you probably want from a solution hosted on-prem. Third, considering the total lifetime costs, running an HCI environment doesn’t cost that much because you have compute and storage and networking combined in a single unit.
Hyperconverged storage platforms players
Like many industrial markets, we have large players that control a considerable percentage of this hyper-converged storage platform market. These are the major industry players. Of course, there are hundreds of more niche players, but these staples provide a good starting point to understand the capabilities offered.
Major hardware players
HPE/SimpliVity
Dell EMC
Nutanix
Pivot3
Major software players
VMware (vSAN)
Maxta
HPE, Nutanix, and Pivot3 provide a single virtualized environment that can be leveraged almost out-of-the-box. And when you think about how these really can be optimized, let me give you a couple of different use cases where these are most efficient.
High throughput analytics: When your business requires high compute capabilities and demand faster compute processing, this type of integrated solution offers many possibilities. Typically, this business case is best applied when heavy data processing needs can benefit from having the storage and compute very close together. This can be a significant advantage for the end-users perception of application and visualization performance.
Virtualized desktops: Running virtualized desktop often requires a wide range of scalability. Over the weekend, for example, you might run 25% of your normal nodes, whereas, during the week, you might have peak times where you’re running 125% of the average weekly for computing. Based on the number of users and volume of workgroups your enterprise supports, the ability to rapidly scale up and down can be advantageous.
COTS specifications for performance: much larger out-of-the-box solutions, like SAP or Oracle, typically have pre-determined specifications in terms of computing, storage, and networking that are required to run the environment to performance standards. Using HCI type of environments is a great way to ensure the setup needed for optimal performance. Once the standard specifications are known, you can scale your hyper-converged infrastructure directly to those needs or overbuild to ensure you’ll hit or exceed performance targets/
What’s in the market today for HCI?
There are hundreds of products that offer similar but not the same functionality. Therefore, it’s essential to consider how each technology component extends existing capabilities before adding technology into an already complex ecosystem. All too often, leaders end up adding technologies because they are best-in-class and end up duplicating technologies in their architecture stack that perform near-identical functions.
Nutanix Acropolis has five key components that make it a complete solution for delivering any infrastructure service:
StarWind is the pioneer of hyper-convergence and storage virtualization, offering customizable SDS and turnkey (software+hardware) solutions to optimize underlying storage capacity use, ensure fault tolerance, achieve IT infrastructure resilience and increase customer ROI.
VxRail, As the only fully integrated, preconfigured, and pre-tested VMware hyper-converged infrastructure appliance family on the market, VxRail dramatically simplifies IT operations, accelerates time to market, and delivers incredible return on investment.
VMware vSAN is a software-defined, enterprise storage solution powering industry-leading hyper-converged infrastructure systems.
IBM CS821/CS822: IBM Hyperconverged Systems powered by Nutanix is a hyper-converged infrastructure (HCI) solution that combines Nutanix Enterprise Cloud Platform software with IBM Power Systems.
Cisco HyperFlex: Cisco HyperFlex. Extending the simplicity of hyper-convergence from core to edge and multi-cloud.
Azure Stack HCI: The Azure Stack is a portfolio of products that extend Azure services and capabilities to your environment of choice—from the data center to edge locations and remote offices. The portfolio enables hybrid and edge computing applications to be built, deployed, and run consistently across location boundaries, providing choice and flexibility to address your diverse workloads.
Huawei FusionCube BigData Machine is a hardware platform that accelerates the Big Data business and seamlessly connects with mainstream Big Data platforms. The BigData Machine provides the high-density data storage solution and Spark real-time analysis acceleration solution based on Huawei’s innovative acceleration technologies.
Each of these technologies adds something specific in terms of functionality and capability extension. Consider which products are already part of your infrastructure and integrate well with potential new technology additions.
Advantages to running an HCI
Hyper-converged infrastructure can offer companies huge benefits and aren’t all associated with pure performance gains.
First, when using hyper-converged infrastructure, you don’t need as many resources to maintain and support the environment. Second, an HCI environment is less complex and more simplified; this removes the conventional layers of microservices that commonly require technical specialization. Third, by eliminating the need for technology resource specialization, maintenance, support, and enhancement resources decrease, adding to cost savings.
Second, there is a financial benefit by having the compute and storage very close together. Almost always, of course, depends on the specific business case; there will be cost-saving realized from this coupled architecture.
Third, major business transformations can be more easily supported. For example, let’s assume that the business pivots and traffic increases by 40%. Usually, this would be beyond what would be generally supported for elastic growth, and therefore there would be a performance hit. However, because this technology is plug-and-play, it’s easy to swap out an existing appliance for a newer appliance with improved capabilities. Of course, these applications can auto-scale up to a limit, but swapping out appliances is a viable option if that limit is hit.
As you consider starting up proof of concepts (POCs) and exploring different ways to provide value to your business customers, evaluating hyper-converged technologies and infrastructures might be a safe way to ensure that performance guarantees are achieved.
Is there a business case for in-storage data processing? Of course, there is, and I’m going to explain why.
Hi, I’m Peter Nichol, Data Science CIO.
Computational storage is one of those terms that’s taken off in recent years that few truly understand.
The intent of computational storage
Computational storage is all about hardware-accelerated processing and programmable computational storage. The general concept is to more data and computers closer together. The idea is that when your data is far away from your compute, it not only takes longer to process, but it’s more expensive. This scenario is common in multi-cloud environments where moving and erasing data out is a requirement, but that requirement comes at a very high cost. So the closer we can move that data to our compute power, the cheaper it will be, and ultimately, the faster we will be able to execute calculations.
Business cases for computational storage
The easier way to understand computation storage is to observe a few examples. These concepts are primarily embedded in startups and are most commonly known as “in-situ processing” or “computational storage.”
First, let’s focus on an example around hyperscalers. Hyperscale is used to do things like AI compute, high throughput video processing, and even composable networking. When we observe organizations like Microsoft, they are incorporating these technologies into their product suites. For example, Microsoft is using computation storage in their search engines with the application of use field-programmable gate arrays (FPGAs). The accelerated hardware enables search engines and can provide those credentials and analytical results in less than microseconds. Also, these capabilities are expanding into other capabilities like Hadoop MapReduce using DataNodes for storage and processing.
Second, architectures that are highly distributed are very effective. Hyperscale architectures build a great foundation to scale computational compute capabilities. The concept of segmenting hardware to software is not new. Even AWS Lambda—typically a data streaming capability—we can deconstruct an application to break out data flow into several parts. This makes managing multiple data streams much more streamlined. For example, data feeds can be individually ingested into a data stream, then AWS Lambda can manage the data funnel from AWS Lambda into computational storage. Once that stream is fed into computational storage, that data stream is more efficient and capable of executing instruction even faster than if not fed into computational storage.
Why look at computational storage now?
Do we as leaders even care about computational compute? Yes, we do. Here’s why.
Looking over the last year or even the previous decade, the way data is stored is designed and architected based on how CPUs are designed to process that data. That was great when the hardware designs aligned to the way data was processed. But, unfortunately, how CPUs were designed and architected over the last ten years has dramatically changed. And as a result, we need to change how we store data to process it more effectively, faster, and cheaper.
The industry trend to adopt computational storage
Snowflake is an excellent example of a product that separates the compute from the storage processing. This results in a perfect opportunity for business leaders to realize the benefits of separating computing from storage. This helps accelerate data read and processing cycle times. The advantage is that users experience faster application and interface responses with faster visualization and presentment of the data requested.
If you’re curious to research additional topics around computational storage, the Storage Networking Industry Association (SNIA) formed a working group in 2018 that has the charge to define vendor-agnostic interoperability standards for computational storage.
As you think about your technology environment and how you’re leveraging and processing data, consider how far your data is from your ability to compute that data and process it analytically. Data needs are growing exponentially, and the demand for computational storage will be tightly coupled to the need to display and visualize organizational data. Your organization might benefit from levering computational storage to connect high-performance computing with traditional storage devices.